Note
Go to the end to download the full example code.
Class-probability uncertainty for multiclass forests
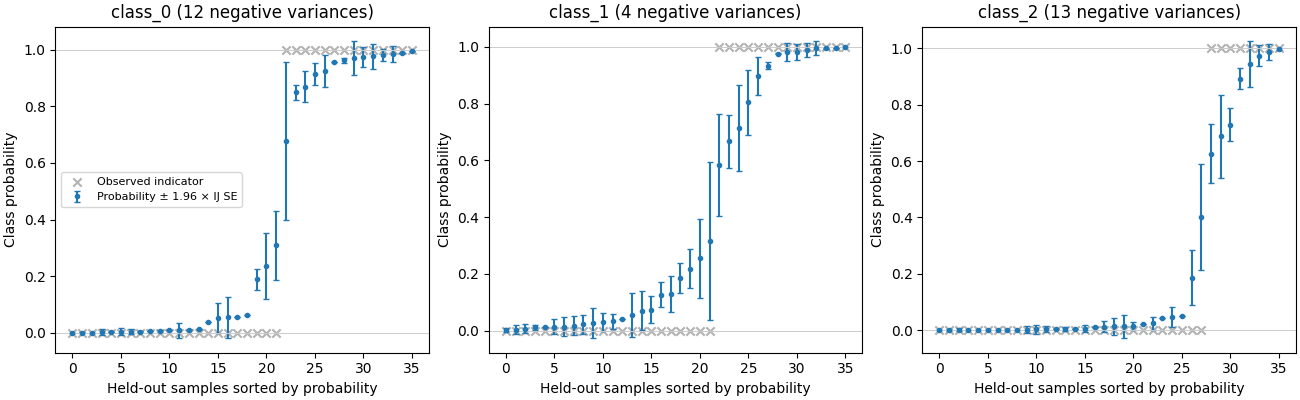
The Wine dataset has three classes. For each class, class_index selects
its column in forest.classes_ and estimates the sampling variance of
predict_proba using the individual trees’ probabilities. No one-vs-rest
refitting is needed. Binary classifiers can use the same API.
The bars below are approximate marginal 95% confidence intervals for fitted probabilities, not prediction intervals for individual outcomes or simultaneous confidence regions for all classes. IJ estimates do not remove model bias. Normal intervals can extend outside [0, 1]; they are deliberately not truncated. Negative raw variance estimates are counted and clipped only for square roots; a zero width produced by clipping is not evidence of certainty.
import numpy as np
from matplotlib import pyplot as plt
from sklearn.datasets import load_wine
from sklearn.ensemble import RandomForestClassifier
from sklearn.model_selection import train_test_split

import forestci as fci

wine = load_wine()
X_train, X_test, y_train, y_test = train_test_split(
    wine.data, wine.target, test_size=0.2, random_state=42
)
forest = RandomForestClassifier(n_estimators=2000, random_state=42, n_jobs=-1)
forest.fit(X_train, y_train)
probabilities = forest.predict_proba(X_test)
inbag = fci.calc_inbag(len(X_train), forest)

fig, axes = plt.subplots(1, 3, figsize=(13, 4), layout='constrained')
for k, ax in enumerate(axes):
    variance = fci.random_forest_error(
        forest, X_train.shape, X_test, inbag=inbag,
        class_index=k, calibrate=False,
    )
    half_width = 1.96 * np.sqrt(np.maximum(variance, 0))
    order = np.argsort(probabilities[:, k])
    ax.errorbar(np.arange(len(X_test)), probabilities[order, k],
                yerr=half_width[order], fmt='.', capsize=2,
                label='Probability ± 1.96 × IJ SE')
    ax.scatter(np.arange(len(X_test)),
               (y_test[order] == forest.classes_[k]).astype(float),
               marker='x', color='0.5', alpha=0.6, label='Observed indicator')
    ax.set(title=f'{wine.target_names[k]} ({np.sum(variance < 0)} negative variances)',
           xlabel='Held-out samples sorted by probability',
           ylabel='Class probability')
    ax.axhline(0, color='0.8', linewidth=0.7)
    ax.axhline(1, color='0.8', linewidth=0.7)
axes[0].legend(fontsize=8)
plt.show()
calibrate=True can mitigate finite-tree noise in these variance
estimates. It does not calibrate predicted probabilities. The calibration
benchmark reports each Wine class separately, and the CI-versus-observed-error
page compares each probability with its corresponding 0/1 class indicator.
Existing binary calls without class_index retain the legacy variance of
hard-vote fractions, which can differ from probability-based uncertainty.
Total running time of the script: (0 minutes 4.216 seconds)